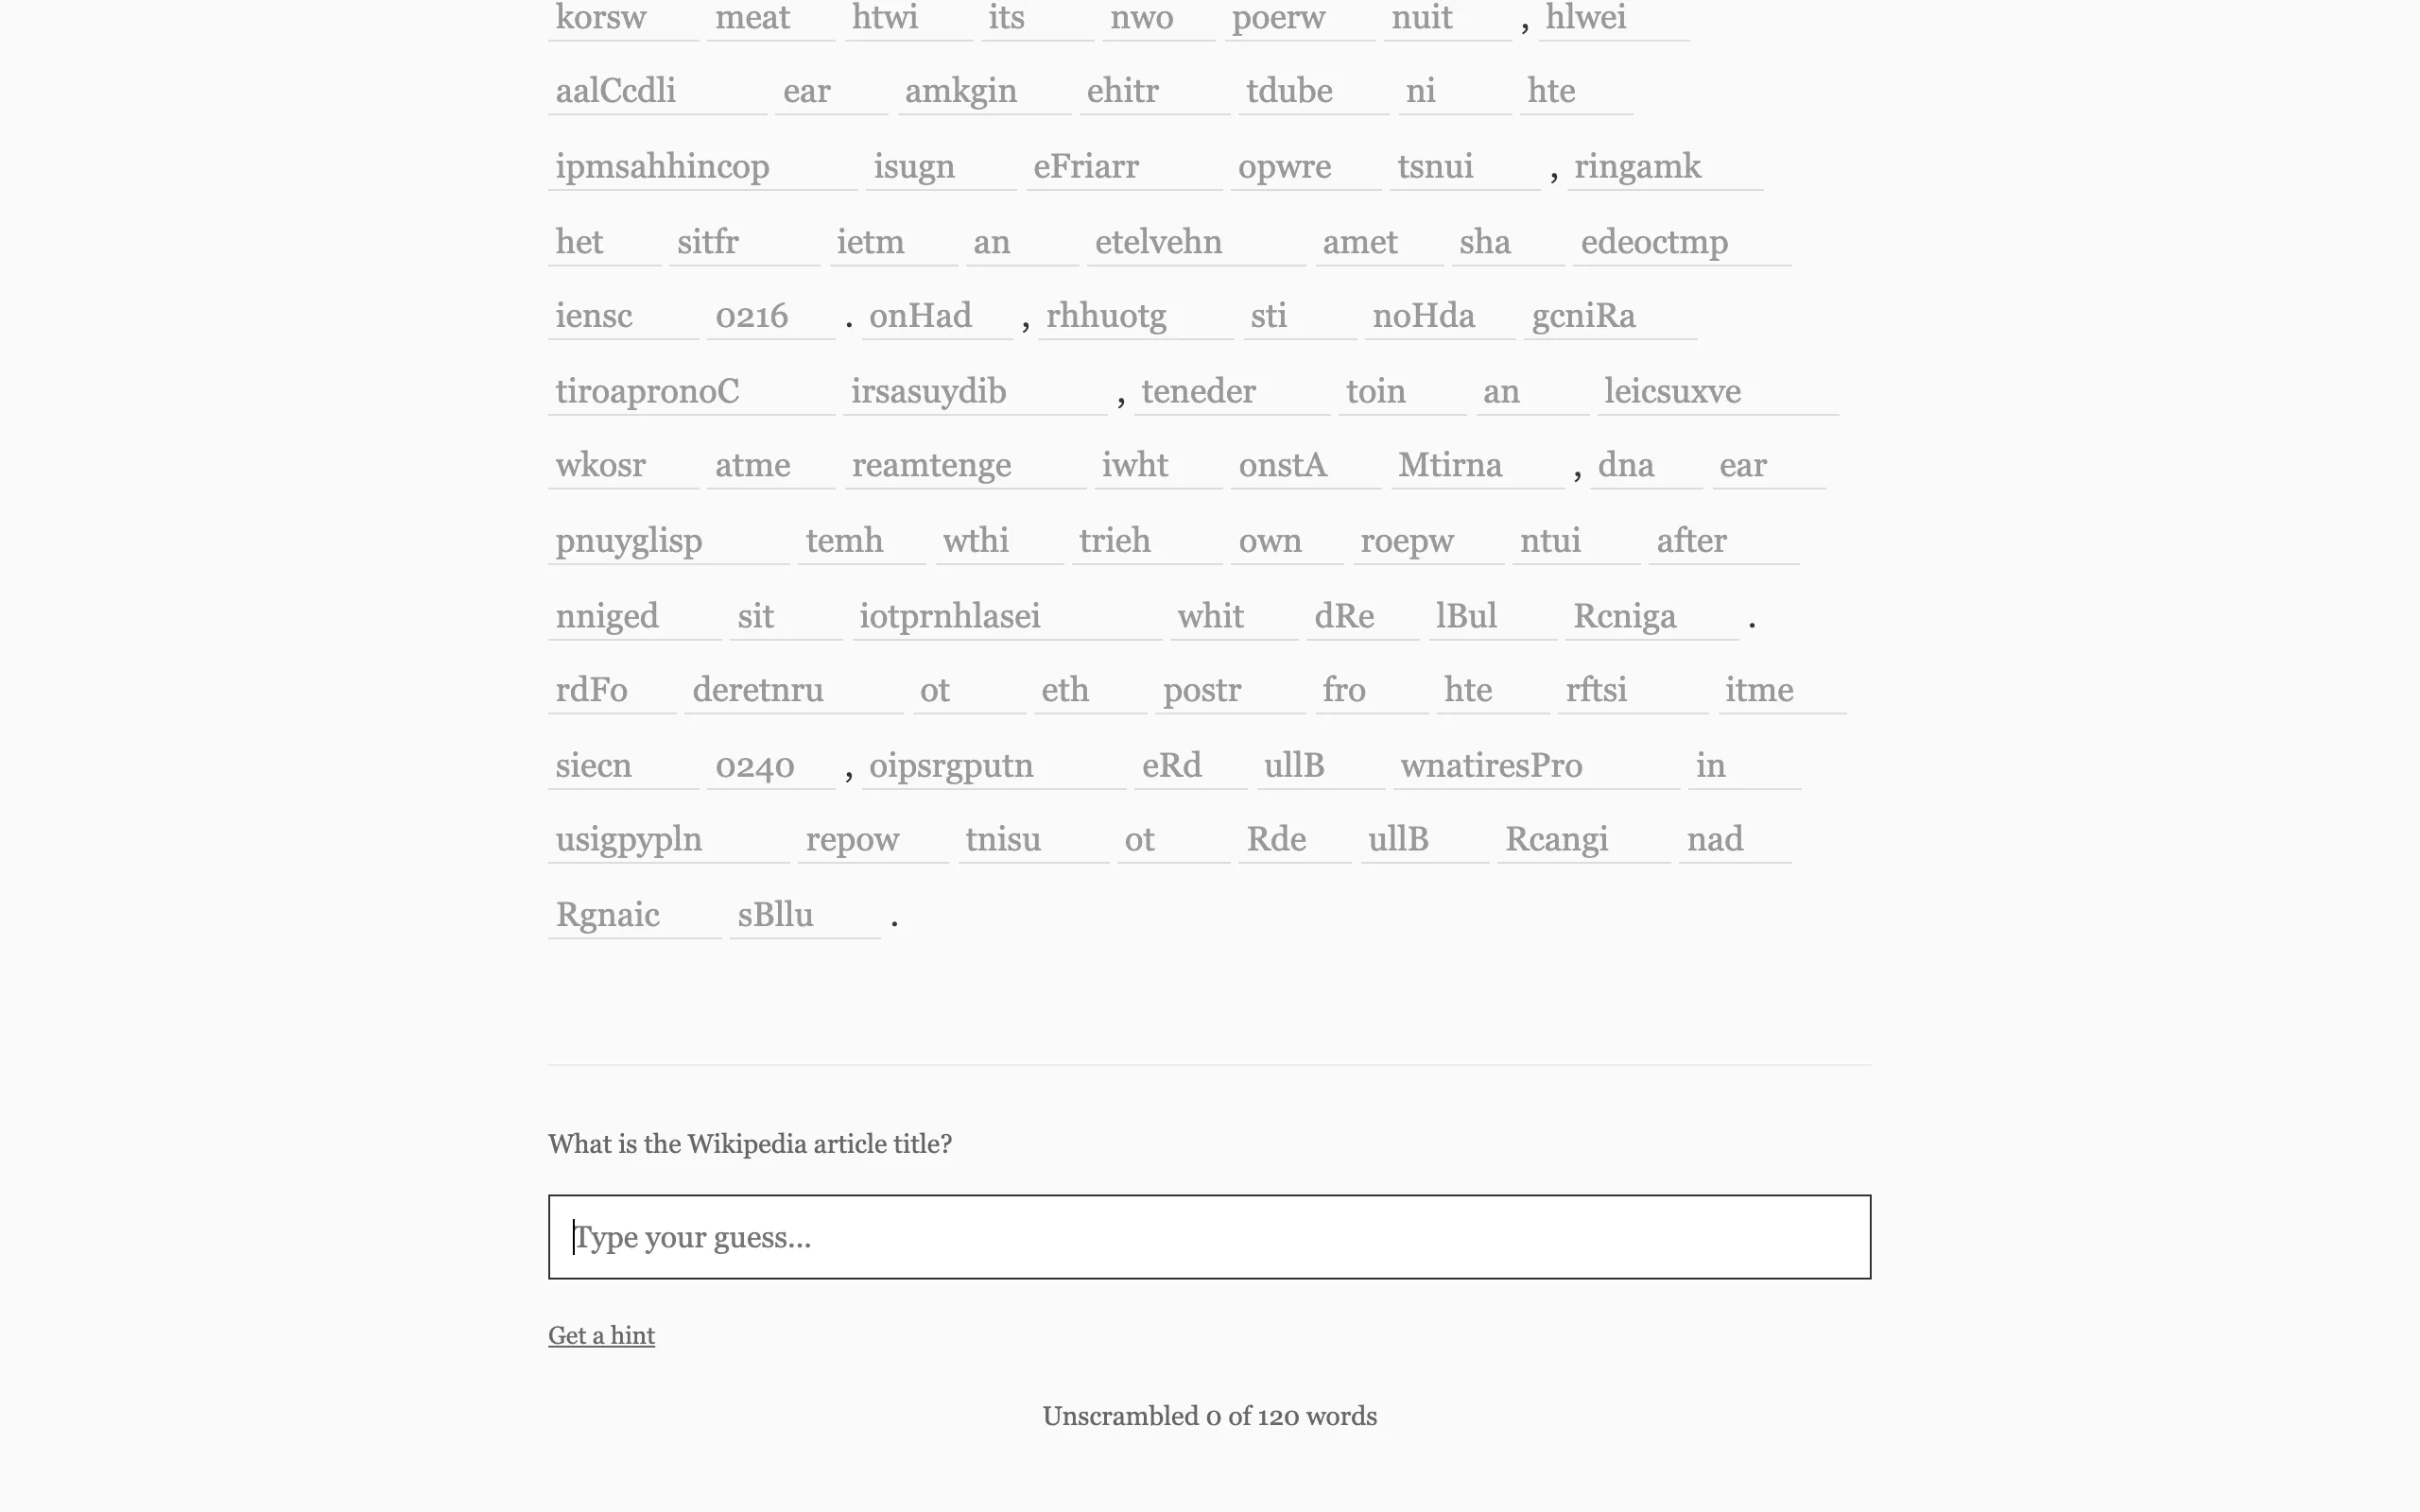
The typoglycemia meme says you can read jumbled text as long as the first and last letters stay put. That's an overstatement, but context does a lot of the work when you read, and I wanted a game that measured how much. So this scrambles every letter of every word, first and last included, and gives you nothing but the words around it.
The game fetches a real article, cuts out four sentences, and shuffles each word in place with punctuation left where it was. You type your guess for each word into its slot and it locks green when you're right. Separately, you can guess the article title at any point. A few unscrambled words tell you the topic, and the topic tells you what the remaining words could be. Hints for the title give the character count, then the first letter, then the first word.
Yesterday's top 500 as a difficulty dial
An article on the United States is far easier to unscramble than one on a species of moth, so I use Wikimedia's pageview API as the difficulty signal. I pull yesterday's 500 most-viewed articles on English Wikipedia, drop the Main Page and anything with a namespace prefix, and slice by rank. Easy is the top 50, medium is 50 to 200, hard is 200 to 500. The top 50 is mostly countries, celebrities, and whatever was in the news, and the hard tier is full of articles I've never opened.
Because the ranking is a day old, the puzzles rotate on their own and I never have to curate a list.
If the article has more than ten sentences I skip the first three to six before taking my four, because the lede usually names the subject outright. Extracts under 200 characters get thrown away and another article drawn. All three difficulties are fetched at once and keep their own state, so switching from easy to hard doesn't lose the easy puzzle. The pageview and extract APIs both allow cross-origin requests, so there's nothing for a server to do.